 By 管理员
1.Project goals and a quick intro to language modeling
We want to build a language model, something like:
- Give it the start of a sentence: “Hello, the weather today”
- Let the model generate what comes next: “Really nice!”
This is called language modeling (Language Modeling), and its core task is:
Given a sequence of tokens, predict the next token.
2. Project modules and what each one does
Building a system like this takes four modules:
| Module | Question | Files |
| 1. Data preparation | What do I train on? How do I turn it into a format the model can learn from? | dataset.py + data/tiny.txt |
| 2. Model structure | How do I build a neural network that predicts the next token? | model.py |
| 3. Model training | How do I train it? How do I pick the loss function and the optimizer? | train.py |
| 4. Model inference | It’s trained — how do I get it to generate text? | generate.py |
3. Data preparation: dataset.py
Neural networks can’t take raw text, so the string has to become a tensor (numbers).
The text we write is a string, for example:
text
Copy and paste
hello world
But the model only understands numbers, so we need:
- Character table: build stoi = {“h”:0, “e”:1, …, ” “:5}
- Character encoding: turn the text into [0, 1, 2, …]
- Sliding window: cut it into small chunks for training (input/label)
We wrap all of this into a single CharDataset class, so the model can copy and edit the data through python.
Reading, cleaning, and batching the data is all handed off to dataset.py.
4. Model structure: model.py
We keep the model architecture in its own file. The model is a standalone component — it gets reused both when training and when using it.
That way we can
- train one model
- then have another script load it to generate text
- or later switch to a different training method while the model structure stays the same
So the model definition lives in model.py, and both the training script and the inference script can import it — that gives us modularity, reuse, and decoupling.
5. Model training: train.py
A dedicated training script keeps the structure clear, makes it reusable, and makes tuning easier.
It’s responsible for:
- loading the data
- initializing the model
- setting up the optimizer
- training the model over many rounds
- saving the weights
Perks:
- change the training data without touching the model
- change hyperparameters without touching the model structure
- train / generate / evaluate separately
6.Model storage directory and format
Trained models live in checkpoints/, saved as .pt files
7. Text generation: generate.py
generate.py can load a trained model and run inference.
| Module | Job | |
| dataset.py | Data preparation — its job is to “eat the data” | |
| model.py | Network structure — its job is to “compute the prediction” | |
| train.py | Training process — its job is to “learn the knowledge” | |
| generate() | Inference script — its job is to “write the sentences” | |
| checkpoints/ | Saves the model so it’s easy to use next time |
8.The actual implementation
So we set up our directory structure like this.
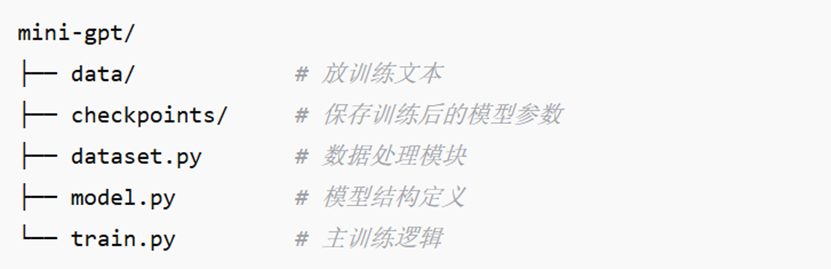
First we add one sentence to data/tiny.txt
“Hello, world! The weather is nice today, let’s go out and play.”
This is the “language corpus” we’re going to train on.
Next we start writing dataset.py, so the model can:
- read the text
- build the character-to-index mapping
- slice it into training pairs
| Feature | Description |
| CharDataset | A character-level dataset class |
| stoi / itos | Dictionaries for converting between characters and numbers |
| __getitem__() | Slices continuous text into input-target pairs: for example, input “你好今”, target “好今日” (the window slides one character forward) |
| load_dataset() | Reads text from a txt file and returns a dataset object ready for training |
Then we start on model.py, putting together the most basic GPT architecture (MiniGPT).
It mainly includes:
- Token Embedding
- Position Embedding
- a simplified Transformer block
- outputs the probability of predicting the next token
model.py is done — we’ve built a minimal but fully functional GPT model.
Let’s walk through its pieces, module by module:
1.SelfAttention
Implements single-head attention (a simplified version of Multi-Head)
- Three Linear layers compute Query, Key, and Value separately
- Uses dot-product attention Q·Kᵀ, divided by a scaling factor
- Uses a tril mask so the model can’t peek at the “future”
- Outputs the weighted V
2. TransformerBlock
The GPT-style stack: LayerNorm → SelfAttention → LayerNorm → FeedForward
- Every layer has a residual connection (x + …)
- Keeps each layer stably trainable
- Simplified version, easy to understand
3.MiniGPT
This is the wrapper for the whole model, and it contains:
| Component | What it does |
| token_embedding | Turns character indices into vectors |
| position_embedding | Adds position information |
| blocks | A stack of Transformer Blocks |
| ln_f | The final normalization layer |
| head | Outputs logits over the vocab, predicting the distribution of the next character |
generate() method
This is our own inference function, and it can:
- Take a seed sequence (character indices)
- Predict the next token each step, sample it, and append it to the sequence
- Decode the whole thing back into a string and return it
Next we write the training script train.py, which we can use to:
- Load the dataset (dataset.py)
- Initialize the model (model.py)
- Train with CrossEntropyLoss and the Adam optimizer
- Print the loss and save the model every few steps
- Generate sample text when training finishes
9.Training results
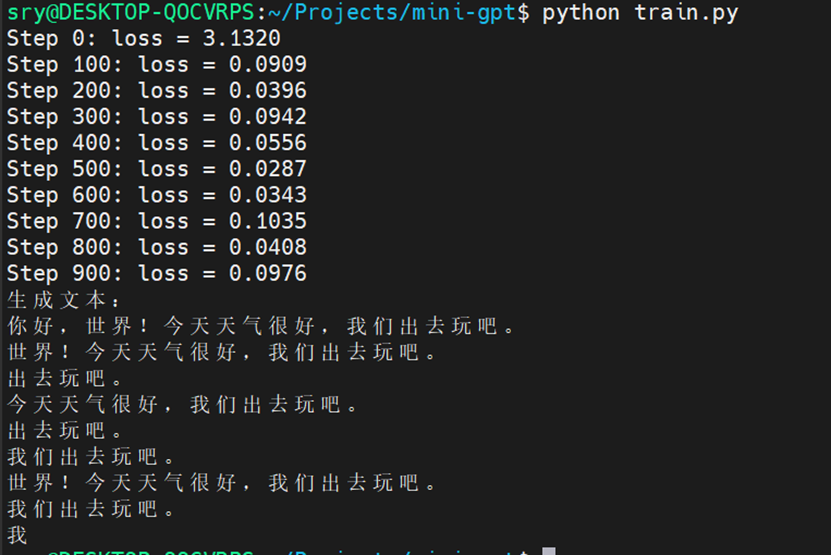
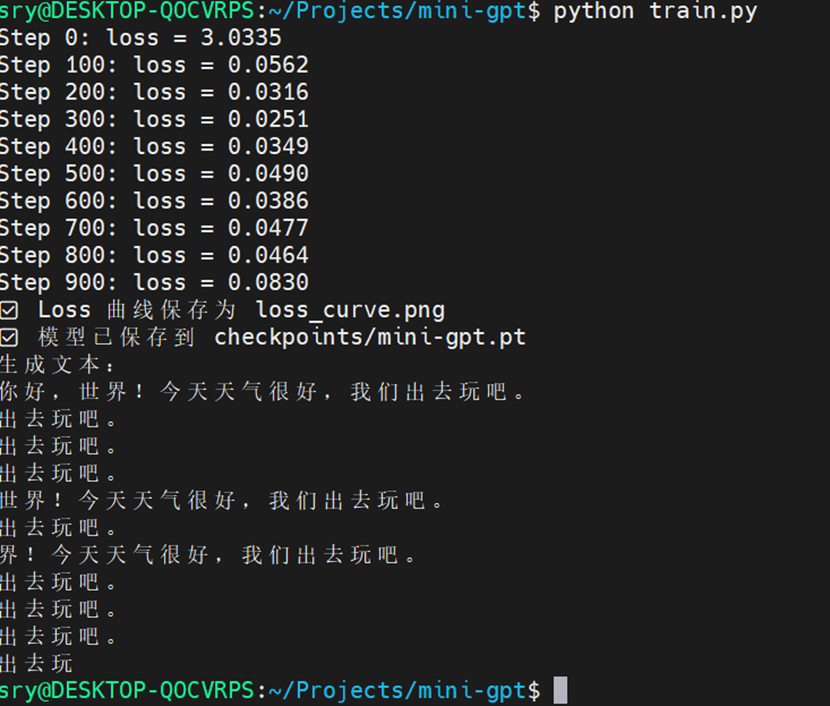
Run it and you get the output: the model trained successfully and the loss came down nicely, which means it has pretty much memorized this sentence. That’s exactly the overfitting you get from tiny data plus a tiny model — it learned to recite by heart but has no generalization, because we only ever fed it one sentence.
What the current results tell us:
- Training is correct: the loss dropped very low, so the model can predict each character precisely.
- The generation logic works: the generate function successfully stitched characters together into new text.
- Memory is excellent: it keeps regenerating “Let’s go out and play”, which shows it memorized the structure
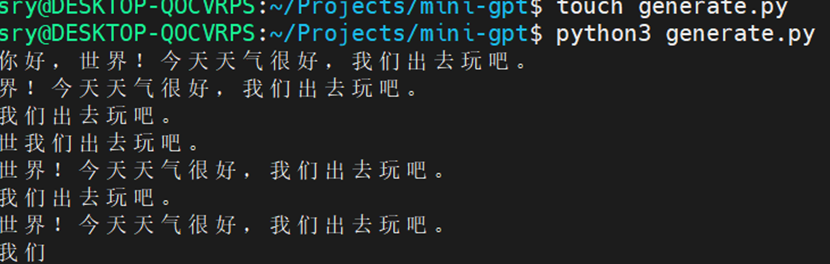
There’s now a model called mini-gpt.pt under checkpoints
We can also use generate.py to load the model and print the results.
10.Visualizing the training process and scaling the model up
Next we add “training loss curve visualization” and try going deeper with the model. Both are extensions of the miniGPT project, gradually turning it into a more complete, more powerful, more analyzable Transformer training system.
Training loss curve visualization (to see whether the model actually “learned”)
It helps you watch the learning process and judge:
- whether the loss is coming down normally;
- whether there’s overfitting or underfitting;
- whether the hyperparameters (like the learning rate) were picked sensibly;
- whether the model is stuck oscillating and not converging.
All you need is to record the loss at each eval_interval in train.py and plot it with matplotlib:
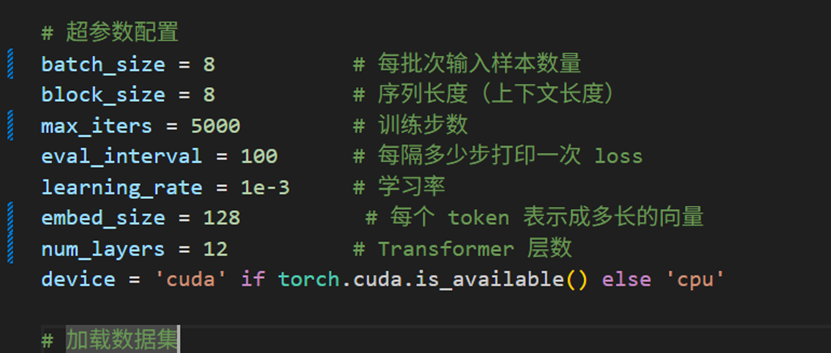
We add the plotting to train.py and set the model’s Transformer to 4 layers.
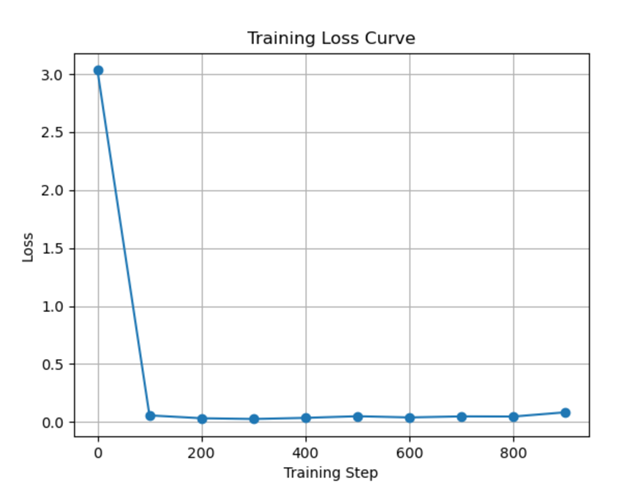
And there’s the chart.
11. Ideas for extending and tuning the model
Here’s what you can try yourself:
1. Add more training text (to improve generalization)
You can swap tiny.txt for multi-sentence text, for example:
Hello, world! The weather is nice today, let’s go out and play.
Hello, I’m an AI agent.
Good morning, today is Friday.
Let’s go play in the park.
That way the model won’t just repeat one sentence.
2. Try generating from a different opening
You can switch to a different starting token, like:
context = torch.tensor([[stoi[‘今’]]], dtype=torch.long).to(device)
print(model.generate(context, max_new_tokens=100, stoi=stoi, itos=itos))
3. A bigger model
model = MiniGPT(vocab_size=vocab_size, block_size=block_size, embed_size=128, num_layers=4).to(device)
But it will demand more GPU memory and training time.
12.Swapping the corpus for Stray Birds
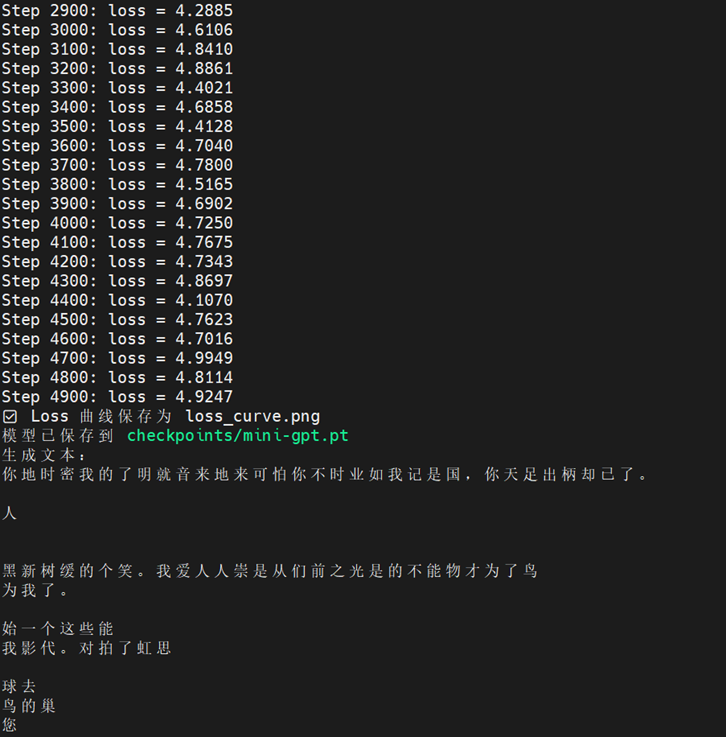
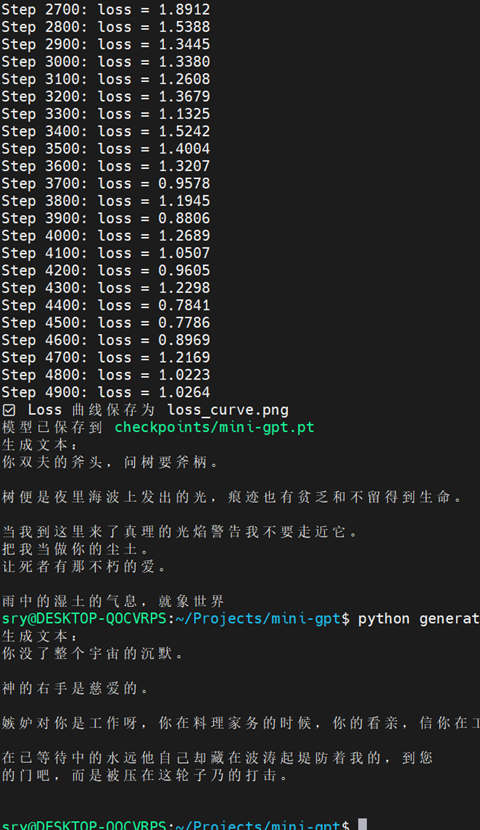
Next I tried replacing tiny.txt with the Chinese text of Stray Birds.
| Loss range | Meaning |
| 0.0 ~ 0.1 | Very good, the model has basically fit the data |
| 0.1 ~ 1.0 | Still learning, converging |
| >1.0 | Poor predictions (common early on), or overfitting/underfitting |
| Huge or NaN | The model has collapsed — maybe gradient explosion, learning rate too high, etc. |
If the model’s predicted probability distribution over the words matches the targets, the loss approaches 0.
If the model guesses at random, the loss stays high.
The big model’s loss is clearly higher than the small one’s. The small model actually trains noticeably better than the big one.
The corpus we’re using (Stray Birds) is itself small, consistent in style, and limited in vocabulary. Using too big a model, for example:
- high embedding dimensions (256, 512)
- many layers (6-layer transformer)
- lots of attention heads
All of that makes the model hard to train well, and it can even overfit badly or get stuck in a local optimum. On a small corpus, a small model picks up patterns much more easily.
9. Training results and summary
Our model has successfully memorized the training corpus and can generate fluent text
A small model suits a small corpus better, keeping overfitting and unstable gradients away
Visualizing the training curve helps you tell whether the model is converging
Next step: systematically test how model size affects training
All the project files from this article!!!!!
https://github.com/spikec137/miniGPT
References:
https://www.shigeku.org/shiku/ws/wg/tagore.htm
Published on August 3, 2025.